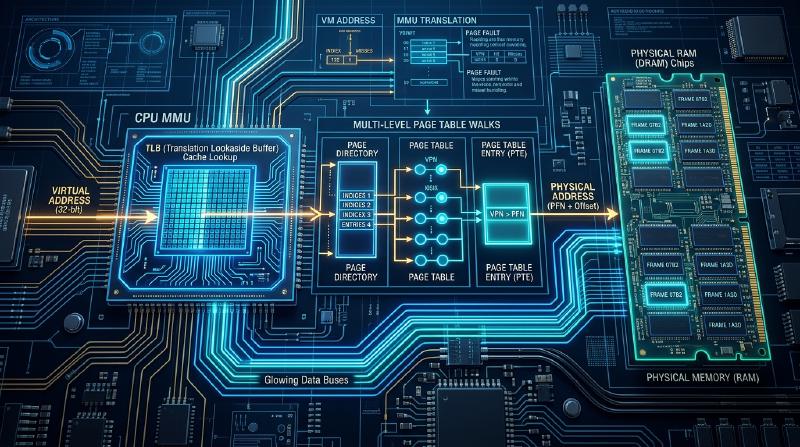
A Complete Anatomy of Virtual Memory and Paging Mechanisms: From MMU to TLB, HugePages, and the Depths of Memory Management
In modern operating systems (OS) and CPU architectures, one of the most complex yet crucial systems is the mechanism of “Virtual Memory” and “Paging”. Behind the memory space that application developers typically use without much thought, the hardware MMU (Memory Management Unit) and the OS kernel work closely together to perform massive amounts of address translation and exception handling in the nanosecond realm.
In this article, we will dissect the deepest parts of the virtual memory system from the perspectives of OS internal structure and computer architecture. We will thoroughly explain low-level mechanisms at the source code and register levels: from the complete bit layout of the page table structure in the x86-64 architecture, the IPI protocol for TLB shootdowns, the complete trace of a page fault in the Linux kernel, the physical mechanism of Copy-on-Write (CoW), memory reclaim algorithms, and the score calculation formula of the OOM Killer.
Chapter 1: The Reason for Virtual Memory’s Existence and Historical Background
Why do computers need virtual memory? In early computer systems, programs accessed specific addresses of physical memory (RAM) directly. However, as multitasking environments became prevalent, this “direct physical addressing method” reached its limits.
1.1 Memory Protection and Complete Separation of Process Spaces
The primary purpose of virtual memory is to “guarantee security and stability”. If Process A were to accidentally (or maliciously) overwrite Process B’s memory, the entire system could crash or confidential information could be leaked. Virtual memory provides each process with the illusion that it has its own “dedicated contiguous memory space”. As a result, memory between processes is strictly separated at the hardware level (MMU), and unauthorized memory access is immediately trapped and treated as a segmentation fault. The separation between user space and kernel space is also achieved by this mechanism, with privilege ring transitions and memory access permission checks being performed by hardware every cycle.
1.2 Breaking the Physical Memory Capacity Barrier and the Philosophy of Demand Paging
It is not uncommon for the amount of memory requested by an application to exceed the installed physical RAM capacity. Virtual memory provides a vast address space larger than physical memory by evicting (swapping out) memory regions (pages) that are not currently in use to secondary storage (HDD/SSD), and loading them back (swapping in) when needed. Furthermore, rather than loading all code and data into memory at the start of program execution, it adopts the philosophy of “demand paging”, loading them into memory only when access occurs, thus achieving both memory savings and faster startup times.
1.3 The Paradigm Shift from Segmentation to Paging
Early x86 processors (like the 80286) used “segmentation,” which managed memory in variable-length blocks. This method calculated logical addresses using a base address plus an offset with registers like CS (Code Segment) and DS (Data Segment). However, segmentation was prone to “external fragmentation” and management was extremely complicated. Later, with the introduction of the 80386, “paging,” which manages memory in fixed-length blocks (usually 4KB), was introduced and became mainstream. Modern 64-bit OSs (Linux and Windows) effectively disable segmentation by using a flat memory model (base address 0, maximum limit) and manage memory solely through paging. Segmentation is now used only for a very few purposes, such as referencing thread-local storage (TLS) via the FS/GS registers.
Chapter 2: The Complete Anatomy of the Multi-level Page Table Structure and Bit Layout in x86-64
In 64-bit architectures (x86-64/AMD64), the virtual address space is vast. In the currently mainstream “48-bit virtual address space”, the hardware MMU walks through a 4-level page table.
2.1 48-bit/57-bit Virtual Address Spaces and the Canonical Form Constraint
While a 64-bit register can represent a massive address space of 16 exabytes, current hardware implementations do not use it all due to cost and complexity. The 48-bit implementation has a constraint where bits 47 through 63 of a virtual address must all have the same value (sign extension). An address that meets this constraint is called a “Canonical Address.”
Consequently, the memory space is structured with a huge unused area in the center (Non-canonical hole), neatly divided into the lower half user space (0x0000000000000000 to 0x00007FFFFFFFFFFF) and the upper half kernel space (0xFFFF800000000000 to 0xFFFFFFFFFFFFFFFF). If an invalid pointer is dereferenced (e.g., a pointer with metadata embedded in the most significant bits), the MMU immediately generates a General Protection Fault (#GP) as a canonical violation. Recently, processors starting from Intel Ice Lake have begun to support an extended 57-bit virtual space (5-level page tables), serving as the foundation for cloud infrastructure handling petabytes of memory.
2.2 Details of the 4-Level Page Table Hierarchy (PML4, PDPT, PD, PT)
To translate a 48-bit virtual address into a physical address, x86-64 uses a 4-level page table hierarchy (a Radix Tree-like data structure). Each table has a size of 4KB and stores 512 64-bit (8-byte) entries (2^9 = 512). The virtual address is divided as follows, functioning as an index for each level:
- Bits 39-47 (9 bits): PML4 (Page Map Level 4) Index - The top level. The CR3 register points to its physical base address.
- Bits 30-38 (9 bits): PDPT (Page Directory Pointer Table) Index
- Bits 21-29 (9 bits): PD (Page Directory) Index - This is the terminal level for 2MB HugePages.
- Bits 12-20 (9 bits): PT (Page Table) Index - The final table for regular 4KB pages.
- Bits 0-11 (12 bits): Page Offset - The offset within the 4KB (4096 bytes) page.
2.3 The Complete 64-bit Layout of a Page Table Entry (PTE)
Each 64-bit entry in a page table is not just a pointer to a physical address; it is a collection of metadata governing powerful access and cache control. The complete bit layout of an x86-64 PTE and its detailed functions are shown below:
- Bit 0 [P] Present: If 1, it exists in physical memory. If 0, it has been swapped out or is unallocated. Accessing it when 0 generates a page fault (#PF) exception.
- Bit 1 [R/W] Read/Write: If 0, it is Read-Only (not writable); if 1, it is Read/Write. Plays an extremely important role in the implementation of CoW (Copy-on-Write).
- Bit 2 [U/S] User/Supervisor: If 0, only accessible in privileged mode (kernel). If 1, also accessible from user mode (Ring 3). Strictly managed by KPTI and SMAP.
- Bit 3 [PWT] Page-level Write-Through: If 1, sets the cache write policy for this page to Write-Through. If 0, Write-Back.
- Bit 4 [PCD] Page-level Cache Disable: If 1, disables caching for this page (Uncacheable). Used for direct access to PCIe device registers via Memory-Mapped I/O (MMIO).
- Bit 5 [A] Accessed: Automatically set to 1 by hardware when the MMU accesses (Reads or Writes) this page. Used as a reference bit by the OS’s LRU algorithm (page reclaim).
- Bit 6 [D] Dirty: Automatically set to 1 by hardware when the MMU “writes” to this page. An essential bit for the OS to determine if write-back to disk (swap out) is necessary.
- Bit 7 [PAT] Page Attribute Table: Combined with PWT/PCD as an index to specify more detailed memory cache types (e.g., WC: Write-Combining). Used for fast bulk transfers to graphics memory (VRAM).
- Bit 8 [G] Global: If 1, the entry is not flushed from the TLB even when the CR3 register is switched (on context switch). Primarily used for pages in the kernel space to avoid the penalty of TLB misses during system calls.
- Bits 9-11 [AVL] Available: 3 bits freely available to the OS (kernel). In Linux, sometimes utilized for swap entry metadata or NUMA node identification.
- Bits 12-51 [PFN] Physical Frame Number: The base address of the translated physical page (Physical Frame Number). Since it is 4KB aligned, the lower 12 bits are always treated as 0.
- Bits 52-62 [AVL/PKU] Available/Ignored: Reserved depending on CPU generation and feature extensions (like Intel MPK: Memory Protection Keys), or available for OS use.
- Bit 63 [XD/NX] Execute-Disable / No-eXecute: If 1, makes the data on this page “non-executable as instructions”. A powerful security mechanism (DEP: Data Execution Prevention) that prevents code injection attacks into data areas, such as via buffer overflows.
Thus, each bit of the PTE is tightly coupled with the OS memory management algorithms (especially swap processing, security protection, and I/O control), serving as an extremely sophisticated design at the boundary interface between hardware and software.
Chapter 3: Hardware Page Table Walks by the MMU and the Wall of Latency
The translation from a virtual address to a physical address is performed by a dedicated hardware circuit called the MMU (Memory Management Unit) located inside the CPU core.
3.1 The Table Walk Mechanism Starting from the CR3 Register
The processor’s control register CR3 stores the physical address of the top-level page table (PML4) of the currently executing process. When an OS like Linux performs a context switch to hand over CPU execution to another process, it rewrites this CR3 register with the new process’s PML4 address. As a result, the entire memory space of the process switches instantaneously.
Here is the conceptual flow:
- Extract the top-level index from the virtual address and read the corresponding entry in the PML4 table pointed to by CR3.
- Extract the PFN from the PML4 entry and calculate the physical address of the next PDPT table.
- Read the corresponding entry in the PDPT table.
- Follow the same process for the PD table and PT table to obtain the base address of the final 4KB physical page.
- Finally, add the 12-bit page offset to construct the complete physical address.
3.2 Memory Bus Access and the Greatest Wall: Latency
The biggest weakness of this 4-level page table walk is “memory access latency”. Translating a single virtual address generates, in the worst case, four accesses to physical memory (reading PML4, PDPT, PD, and PT). The access latency of modern DRAM is about 50 to 100 nanoseconds. If all four memory accesses miss the CPU caches (L1/L2/L3) and reach DRAM, this alone will cause a stall of several hundred nanoseconds. Considering a CPU clock cycle is around 0.3 nanoseconds (at 3GHz), this equates to a fatal delay of thousands of cycles, completely starving and halting the CPU pipeline. To break through this severe performance wall, the TLB, explained next, was designed.
Chapter 4: TLB Architecture in Multi-core Environments and the Agony of Shootdowns
The TLB (Translation Lookaside Buffer) is a “cache of virtual-to-physical address translation results” built into the MMU, consisting of ultra-fast SRAM (or CAM: Content Addressable Memory).
4.1 TLB Hierarchical Structure and Optimization via PCID (Process-Context Identifier)
In modern CPUs, the TLB also has a hierarchical structure of L1/L2. The L1 D-TLB (for data) and L1 I-TLB (for instructions) have a very small capacity (dozens of entries) but respond in a single cycle. The L2 TLB has hundreds to thousands of entries and responds in a few cycles. When an entry is not present in the TLB (TLB miss), the aforementioned hardware table walk (page walk) occurs. To assist this, a PWC (Page Walk Cache) dedicated to page walks is also implemented.
Because the meaning of virtual addresses changes when a process switches, conventionally (in early x86), the entire TLB was flushed when CR3 was rewritten. However, this caused frequent TLB misses immediately after a context switch, severely degrading performance. To solve this, a technology called PCID (Process-Context Identifier) was introduced (known as ASID in the ARM architecture). By attaching a 12-bit ID (tag) to the TLB entry to uniquely identify a process, it became possible to retain the TLB entries of previous processes even after a context switch, dramatically improving performance in multi-process environments like web servers and databases.
4.2 The Inter-Processor Interrupt (IPI) Protocol for TLB Shootdown
In a multi-core environment, the virtual memory system faces very troublesome synchronization issues. For example, suppose a process running on Core 0 (CPU0) frees a specific memory region with munmap() and invalidates the PTE in the page table (Present = 0). However, Core 1’s (CPU1) local TLB might still retain “stale translation information (Stale TLB Entry)” from that virtual address to the physical address as a cache.
If left unaddressed, Core 1 could access the freed memory, leading to severe security holes like destroying data allocated to another process or reading confidential information. To prevent this, the OS must force Core 1 to delete the relevant entry from its TLB. This is called a TLB Shootdown.
TLB shootdown is strictly executed in the following steps (IPI protocol):
- Initiator (Core 0): After updating the page table (clearing the PTE), it issues a memory barrier (like
mfence) and sends an IPI (Inter-Processor Interrupt) to the local APIC (Advanced Programmable Interrupt Controller) of the target cores (Core 1). - Wait (Busy-Wait): Core 0 waits via a spinlock until all target cores have finished processing the interrupt.
- Target (Core 1): Upon receiving the IPI, it immediately interrupts the currently executing user code and transitions to the kernel’s interrupt handler (e.g.,
flush_tlb_funcviasmp_call_functionin Linux). - Execute Flush: Core 1 invalidates the entry for the specified virtual address from its local TLB (using the
INVLPGinstruction on x86, or reloading CR3 for a full flush). - Completion Notification: Core 1 writes a completion flag in memory to release Core 0’s wait, then returns to the interrupted process (
iret).
Performance Bottlenecks and Scalability Limits: Since TLB shootdown involves hardware IPI issuance, interrupt context switching, pipeline flushing, and inter-core spinlock waiting, it is an extremely high-cost operation consuming thousands to tens of thousands of cycles. As the number of cores increases to 16, 64, or 128, this synchronization cost increases exponentially, becoming a severe impediment to scaling multi-threaded applications in cloud servers and HPC (especially those that frequently allocate and free memory).
Chapter 5: Complete Trace of Page Fault Handling in the Linux Kernel
When a program accesses an area where the Present bit of the page table is 0, or an area without proper permissions (e.g., trying to write to Read-Only memory, or accessing kernel memory from user mode), the MMU issues a page fault exception (Exception 14, #PF on x86). From here, a journey into the deep exception handling of the Linux kernel begins.
5.1 Control Flow of Page Faults and Tracing Architecture-Dependent Parts
In the x86-64 Linux kernel, the function call graph (call trace) when a page fault occurs looks as follows. Control transfers from the architecture-dependent low-level handler to the architecture-independent generic memory management subsystem.
asm_exc_page_fault(Assembly language: arch/x86/entry/entry_64.S)- The CPU detects the exception, hardware sets the faulting virtual address in the
CR2register, saves the register state to the interrupt stack, and jumps to the kernel’s entry point.
- The CPU detects the exception, hardware sets the faulting virtual address in the
exc_page_fault()(C language: arch/x86/mm/fault.c)- The architecture-dependent fault handler. It analyzes the error code (Read/Write, User/Kernel, PF, etc.) and checks for interrupt contexts.
do_page_fault()/do_user_addr_fault()- Determines whether the fault occurred in kernel space (e.g., a bug or vmalloc area) or user space. If in user space, it searches the target process’s memory map (the red-black tree/VMA list of
vm_area_struct) to verify if the address belongs to a valid region (checking if it’s a segmentation fault).
- Determines whether the fault occurred in kernel space (e.g., a bug or vmalloc area) or user space. If in user space, it searches the target process’s memory map (the red-black tree/VMA list of
handle_mm_fault()(C language: mm/memory.c)- This is where the architecture-independent core function begins. It traverses each level of the page table (PGD -> P4D -> PUD -> PMD -> PTE), allocating intermediate directories (like
pmd_alloc) if they haven’t been allocated yet, to pinpoint the final PTE address.
- This is where the architecture-independent core function begins. It traverses each level of the page table (PGD -> P4D -> PUD -> PMD -> PTE), allocating intermediate directories (like
5.2 The Essence of Memory Allocation: Branching from handle_mm_fault
handle_mm_fault() branches out to actual page allocation processes depending on the state of the identified PTE (whether the PTE is empty, swapped out, or has a permission error).
do_anonymous_page()(The Zenith of Demand Paging): Called when the PTE is completely empty (zero). It handles the first access to an anonymous page that is not tied to a file, such as the expansion of the heap (brkormmapbehindmalloc) or the stack. Here, the kernel secures a physical memory frame from the Buddy System for the first time, clears it to zero, and maps it to the PTE. This saves unused memory.do_fault()/__do_fault()(File-backed Paging): Called on the first access to things likemmap‘ed files. It reads file data from the page cache or calls the file system driver (like ext4 or xfs) to load data from disk, mapping it to the page table.do_swap_page()(The Pain of Swap-in): Called when the PTE’s Present bit is 0, but swap area offset information is recorded in other flag bits. It loads the data back from disk (swap partition or swap file) to physical memory. Because it involves disk I/O, the process enters a prolonged Sleep (blocked) state here.do_wp_page()(Copy-on-Write): The CoW process detailed later. Called when attempting to write to a page where Present=1 but there is no Write permission.
5.3 Physical Mechanism of Copy-on-Write (CoW) and the Magic of Reference Counting
The fork() system call, which is the cornerstone of Linux process creation, operates extremely fast thanks to a lazy evaluation mechanism called CoW (Copy-on-Write). Even if a parent process uses several GBs of memory, fork() completes in an instant. Here’s the physical mechanism behind it.
- Page Table Sharing:
When
fork()is called, the kernel copies the parent process’s page tables directly to the child process. However, the physical memory itself is not copied at all. The parent and child PTEs point to exactly the same physical memory (frames). - Forced Setting of Read-Only Bits (Write-Protect):
At this time, the kernel forcibly rewrites the
R/Wbit of the PTEs for all shared pages to0(Read-Only) (including all data regions that were originally writable). - Incrementing the Reference Count:
The kernel structure managing the target physical page (the
_refcountinstruct page) is incremented, marking it as “referenced by two processes.” - Writing and Page Faults (Triggering do_wp_page):
If either the parent or child attempts to write to a shared variable or heap area, the hardware MMU detects
R/W=0and immediately generates a page fault. - Duplication of the Page:
do_wp_page()is called from the page fault handler. The kernel checks the VMA flags and determines, “This is not an illegal access, but a legitimate fault due to CoW.” It secures a new physical page from the buddy system and copies the entire data of the original page (copy_page). - Updating the PTE and Decrementing Reference Count:
It redirects the PTE of the writing process to the new physical page and sets the
R/Wbit to1(Read/Write enabled). The reference count of the original physical page is then decremented. If the reference count drops to 1, it means the other process now exclusively owns that page, so the next time that process causes a fault, the kernel only needs to set the R/W bit back to 1 without copying memory (page reuse).
Thus, CoW is an artistic algorithm beautifully fusing the MMU’s hardware protection (Read-Only trapping) with the kernel’s software control, realizing dramatic memory savings and fast process startups.
Chapter 6: The Depths of Memory Reclaim Algorithms and the Condemnation of the OOM Killer
Physical memory is finite. When a system has been running for a long time and file caches or process heaps exhaust memory, the OS must free and reclaim existing memory regions to secure new memory. This memory reclaim subsystem is one of the most complex and difficult areas in the Linux kernel.
6.1 Active/Inactive LRU Lists and Pseudo-LRU Algorithms
The Linux kernel uses LRU (Least Recently Used) lists to manage and track physical pages. However, managing all pages with a strict LRU is impossible due to lock contention and traversal costs. Therefore, it adopts a pseudo-LRU algorithm (a derivation of the Clock algorithm) using two queues (lists): the “Active list” and the “Inactive list”.
- Active List: A collection of “hot” pages accessed frequently recently. These are not targets for reclaim.
- Inactive List: A collection of “cold” pages not accessed for a while. Pages are candidate for reclaim starting sequentially from the tail.
How does the kernel know a page has been accessed? This is where the Accessed bit (A bit) of the PTE, explained in Chapter 2, comes into play. The kernel (kswapd) periodically scans the page tables, reads the A bit from the PTE, records the access history on the software side, and then clears the A bit to 0. If the A bit is set to 1 again by hardware, the page stays in the Active list or is promoted from Inactive. If not set, it is gradually demoted toward the tail of the Inactive list.
6.2 The kswapd Daemon and the Terror of Direct Reclaim
When free memory (Free Pages) falls below a specific threshold (watermark: low), a kernel background thread named kswapd (existing for each NUMA node) wakes up.
kswapd takes pages from the tail of the Inactive list.
- If it’s a clean file cache (unmodified file data), it simply drops it to free memory.
- If it’s a dirty file cache, it writes it back to disk (Writeback) before dropping it.
- If it’s an anonymous page (process heap or stack), it writes it out to the swap area (swap out).
It continues this background work until free memory reaches the
highwatermark.
However, if the application’s memory allocation rate (memory pressure) is extremely high and kswapd’s reclaim speed cannot catch up, causing free memory to break the extreme threshold (min watermark), Direct Reclaim is triggered.
Direct Reclaim is a mechanism where memory reclaim processes (dropping caches or swapping out) are executed synchronously directly in the context of the process that requested memory (the application itself). When entering direct reclaim, the execution of the application (completion of malloc or page faults) completely stalls, becoming a direct cause of severe performance degradation (latency spikes) lasting from hundreds of milliseconds to seconds. Tuning (such as adjusting vm.swappiness and watermarks) is indispensable to avoid this in databases and real-time systems.
6.3 OOM Killer Score Calculation and Process Condemnation
If memory still cannot be secured even after direct reclaim, with swap areas exhausted and caches completely stripped away, the Linux kernel summons the OOM (Out Of Memory) Killer as a last resort.
To prevent the entire system from falling into a memory exhaustion panic (kernel crash or complete freeze), the OOM Killer reclaims memory by forcefully terminating (SIGKILL) a process that consumes a massive amount of memory. There is a cold algorithm to determine the victim.
The decision of which process to kill is based on an evaluation value called oom_score (calculated by the oom_badness() function in the kernel’s mm/oom_kill.c).
Basic OOM Score Calculation Logic (Concept):
- Base Score: The proportion of the total memory consumed by the memory currently used by the process (RSS: Resident Set Size + page table size + swap usage). Maximum 1000 points. In short, processes consuming more memory (like those with memory leaks) are more likely to be killed.
- Root Privilege Penalty Mitigation: Processes running with root user privileges (such as core system daemons) are likely essential for maintaining the system, so their scores are slightly discounted (reduced), making them harder to kill.
- User Adjustment Value (OOM Score Adj): The value of
/proc/[pid]/oom_score_adj(from -1000 to +1000) is added. System administrators can use this to control the behavior of the OOM Killer. A process with this value set to -1000 (e.g., sshd, kubelet, database master processes) becomes “exempt from the OOM Killer (invincible)”.
When the OOM Killer triggers, it outputs a message like “Out of memory: Killed process 1234 (java)” along with a detailed dump of the process list, scores, and memory states at that time in the kernel log (dmesg or /var/log/messages). By understanding these logs and the score calculation mechanism, system administrators can investigate the causes of unexpected process terminations and configure appropriate resource limits (cgroups or ulimit).
Chapter 7: Latest Ultra-Fast Memory Techniques and Hardware Security
7.1 The Power of 2MB/1GB HugePages and the Pros and Cons of THP
A powerful means to solve the TLB miss and table walk delays described in Chapters 3 and 4 is the “HugePage”. Instead of standard 4KB pages, it uses massive pages of 2MB (pointing directly to the physical address at the Page Directory level, skipping the PT hierarchy) or 1GB (pointing directly at the PDPT level).
Because one TLB entry can cover a vast memory area (512 times or 260,000 times that of 4KB), TLB misses are drastically reduced. In databases that randomly access large amounts of memory (Oracle, PostgreSQL) or virtualization environments (KVM/QEMU), using HugePages is a mandatory performance tuning item.
Linux’s THP (Transparent Huge Pages) is a mechanism where a kernel background thread (khugepaged) automatically merges (defragments) contiguous 4KB pages into 2MB HugePages without the application being aware. However, in heavily fragmented memory environments, this merging process (memory compaction) itself consumes significant CPU and causes latency spikes. Therefore, for in-memory KVS like Redis, disabling THP (never or madvise) is recommended.
7.2 Kernel Page-Table Isolation (KPTI) and the Price of Meltdown Mitigation
The speculative execution vulnerability discovered in CPUs in 2018, “Meltdown (CVE-2017-5754)”, was a fatal flaw shaking the foundation of hardware, allowing user processes to illicitly read the kernel’s memory space (cache).
The OS-side mitigation introduced for this was KPTI (Kernel Page-Table Isolation) (initially called KAISER).
Conventionally, to reduce context switch overhead, the entire kernel area was mapped into the upper half of the page table even during user space execution (assuming privilege checks would be performed via the U/S bit of the PTE, and access would be denied). However, speculative execution bypassed this privilege check.
After introducing KPTI, a “minimal shadow page table (User PGD)” that unmaps most of the kernel during user execution is used. When transitioning to kernel space via a system call or interrupt, it is strictly necessary to switch the CR3 register and reload the full kernel page table (Kernel PGD).
While this completely guaranteed security, it introduced a non-negligible performance overhead ranging from a few percent to over ten percent in I/O-intensive applications (like web servers or DBs that heavily use syscalls) due to the high-cost CR3 switching (and management of PCID/TLB flushing) on every system call or interrupt.
7.3 Evolution of Direct I/O and Zero-Copy Technology
To optimize file I/O, the OS applies virtual memory mechanisms to their limits.
Using the mmap() system call directly maps file contents into the virtual address space. Accessing it triggers a page fault, loads file data into the page cache, and makes it directly accessible as a pointer from user space.
Furthermore, in network transmission/reception or storage I/O, zero-copy technology is utilized to eliminate CPU-driven data copying between the kernel space (page cache) and user space buffers (copies accompanying context switches). System calls like sendfile(), or newer technologies like io_uring and AF_XDP, cooperate with the DMA (Direct Memory Access) controllers of NICs or NVMe drives, manipulating page table PTEs to directly “remap” kernel pages into user space, reducing memory copy overhead to absolute zero. Here, too, clever manipulation of page tables operates as the fundamental mechanism.
Conclusion
Virtual memory and paging mechanisms are a highly advanced symphony performed by the OS kernel and CPU (hardware). From setting a 1-bit flag in a page table, the agony of spinlocks surrounding TLB shootdowns, the magic of memory via CoW reference counting, to the cold heuristics of the OOM Killer, their depths are packed with the wisdom of computer science on “how to safely and swiftly abstract limited physical resources to give processes the illusion of infinity.”
Understanding low-level mechanisms is essential not only for optimizations in systems programming languages like C/C++ and Rust (such as cache-line-aware data structure design and effective use of mmap) but also for deeply understanding the behavior of garbage collection (GC) stop-the-world (STW) pauses and memory allocators (jemalloc or tcmalloc) in high-level languages like Go and Java. By peeling back the veil of the system’s “magic” and feeling the pulse of the hardware and kernel firsthand, the path will open up to becoming an outstanding architect capable of designing more refined, scalable software.