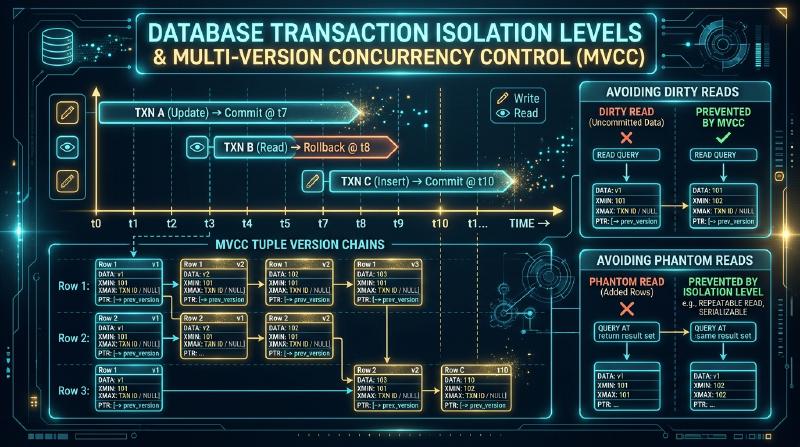
Database Transaction Isolation Levels and MVCC: The Reality of ACID and Multi-Version Concurrency Control
In modern software architecture, Relational Database Management Systems (RDBMS) continue to be the cornerstone of data persistence. At their core is the concept of “transactions,” and particularly the ACID properties (Atomicity, Consistency, Isolation, Durability), which are widely recognized as the foundational theory for building robust systems. However, among the ACID properties, “Isolation” is the area where the greatest divergence between theory and practice exists.
In this article, we will delve deeply from an extremely detailed, academic, and practical perspective into the historical background of database transaction isolation levels, the limitations of the ANSI SQL-92 standard, and the internal structure of Multi-Version Concurrency Control (MVCC) adopted by modern database engines. In particular, we will dissect the decisive differences in the MVCC implementations of two major open-source RDBMSs, PostgreSQL and MySQL (InnoDB), and cover everything up to Serializable Snapshot Isolation (SSI), the forefront of distributed databases, delivering an epic piece of over 12,000 characters.
Chapter 1: The Myth of ACID Properties and the Dilemma of Concurrency
1.1 The Ideal of Serializability
The ultimate ideal that the Isolation of transactions aims for is “Serializability.” This refers to the property that even if multiple transactions are executed concurrently at the same time, the result of their execution is “equivalent to the result of executing the transactions serially one by one in some order.”
When transactions $T_1$ and $T_2$ are executed simultaneously on a system, no matter how the interleaving (crossing of operations) by concurrent execution occurs, if the final state of the database perfectly matches the result of executing them in the order of “$T_1 \rightarrow T_2$” or “$T_2 \rightarrow T_1$”, that schedule is defined as serializable. As long as this serializability is guaranteed, application developers can focus entirely on building business logic without having to worry at all about data inconsistencies caused by concurrent processing (such as race conditions or inappropriate overwrites).
1.2 The Performance Collapse of Lock-Based Serialization
In early database systems, a strict locking mechanism called “Two-Phase Locking (2PL)” was adopted to guarantee this serializability. In 2PL, a transaction must acquire a lock (shared lock or exclusive lock) before reading or writing data (Phase 1: Growing Phase), and releases all locks at the end of the transaction (at commit or rollback) (Phase 2: Shrinking Phase).
However, this strict locking mechanism had a fatal flaw. That was the “extreme degradation of performance.”
- Read operations block write operations.
- Write operations block read operations.
- Increased wait times due to lock contention and frequent deadlocks.
As traffic grew and a large number of users accessed the database simultaneously, perfect serialization by 2PL became a bottleneck for the system, and throughput plummeted rapidly. Systems faced a trade-off dilemma between “data consistency” and “concurrency performance (throughput).”
1.3 The History and Compromises of Concurrency Control
To solve this dilemma, database engineering researchers introduced the concept of “Isolation Levels.” This is a “product of compromise” that improves concurrency performance in exchange for partially relaxing complete serializability and allowing the occurrence of certain data inconsistencies (Anomalies). It allowed developers to choose the balance between consistency and performance according to the requirements of the application.
Chapter 2: The ANSI SQL-92 Standard Isolation Levels and Their Criticism
2.1 The Definition of Isolation Levels by the ANSI SQL-92 Standard
The SQL standard “SQL-92” established in 1992 defined four isolation levels based on three representative anomalies (Phenomena) that can occur due to concurrent processing.
The 3 Defined Anomalies (Phenomena)
- Dirty Read: A phenomenon where a transaction $T_1$ updates data, and while it is not yet committed, another transaction $T_2$ reads that uncommitted data. If $T_1$ is rolled back, $T_2$ would have read phantom data that does not exist.
- Non-repeatable Read: A phenomenon where, between the time a transaction $T_1$ reads the same row twice, another transaction $T_2$ updates and commits that row. The results of $T_1$’s first and second reads will differ.
- Phantom Read: A phenomenon where, while a transaction $T_1$ reads multiple rows with a specific search condition, another transaction $T_2$ inserts (or deletes) a new row that matches that condition and commits. If $T_1$ searches again with the same condition, the number of rows will have increased or decreased.
The 4 Isolation Levels by SQL-92
SQL-92 defined isolation levels according to the degree to which they prevent the occurrence of these anomalies.
- Read Uncommitted: Allows Dirty Reads.
- Read Committed: Prevents Dirty Reads but allows Non-repeatable Reads and Phantom Reads.
- Repeatable Read: Prevents Dirty Reads and Non-repeatable Reads but allows Phantom Reads.
- Serializable: Prevents all anomalies and guarantees complete serializability.
2.2 The Criticism Paper by Berenson et al. “A Critique of ANSI SQL Isolation Levels”
At first glance, the definitions of the SQL-92 standard appear very clear and logical. However, a paper published in 1995 titled “A Critique of ANSI SQL Isolation Levels” by giants of the database world such as Hal Berenson, Jim Gray (Turing Award winner), and Phil Bernstein dealt a devastating blow to this ANSI standard definition.
The main flaws of the SQL-92 standard pointed out in this paper are as follows.
1. The Implicit Assumption of Lock-Based Systems
The definition of SQL-92 implicitly assumed that “the database is implemented with lock-based concurrency control (2PL).” However, in the 1990s, databases adopting MVCC (described later) and other Optimistic Concurrency Control (OCC) methods had already begun to emerge, and definitions of anomalies premised on locks were becoming obsolete.
2. Ambiguity and Incompleteness of the Definitions
It was pointed out that the three anomalies defined in SQL-92 (Dirty Read, Non-repeatable Read, Phantom Read) alone could not cover all anomalies that could occur in concurrent processing. For example, there is a phenomenon called “Dirty Write”. This is a phenomenon where data written by an uncommitted transaction is overwritten by another uncommitted transaction, but the SQL-92 standard makes no mention of Dirty Writes. Even though all isolation levels (including Read Uncommitted) must prevent Dirty Writes (otherwise the internal consistency of the database would collapse), the standard specification did not touch on this point.
3. Discovery of New Anomalies
The paper defined several new anomalies that did not exist in the SQL-92 standard. Two representative examples are:
- Lost Update: A phenomenon where two transactions simultaneously read the same data, and when each writes back its calculated result, one update overwrites and erases the other update.
- Write Skew: A phenomenon peculiar to Snapshot Isolation, which will be described later.
The paper by Berenson et al. proved that the SQL-92 standard failed to define isolation levels mathematically and strictly, and caused a massive shock in the database industry. In modern database theory, the isolation level definitions of ANSI SQL-92 are treated as “something to learn as historical background” and “insufficient as strict technical definitions.”
Chapter 3: Snapshot Isolation and Write Skew
3.1 The Difference Between Repeatable Read and Snapshot Isolation
What drew particular attention in the paper by Berenson et al. was the proposal of a new isolation level called “Snapshot Isolation (SI)”.
In many databases that adopt MVCC (such as PostgreSQL and Oracle), the reality of the isolation level provided as “Repeatable Read” is actually this “Snapshot Isolation.” In Snapshot Isolation, each transaction reads from a consistent “snapshot (a static state of the past)” of the database at the time the transaction begins.
- Updates by other transactions made after the start of the transaction are completely invisible (preventing Non-repeatable Reads).
- Because the very existence of records is fixed at a point in time in the past, INSERTs by other transactions are also invisible (preventing Phantom Reads).
In other words, Snapshot Isolation not only meets the requirements of “Repeatable Read” defined by SQL-92, but often prevents even “Phantom Reads.” So, is Snapshot Isolation equivalent to “Serializable”? The answer is “No.” This is because Snapshot Isolation has a fatal, non-serializable anomaly called “Write Skew”.
3.2 The Doctor’s On-Call Duty Problem and Write Skew
The most famous example to understand Write Skew is the “doctor’s on-call (duty) system.”
[Business Rule] Suppose there is a hospital shift management system with a rule that “at least one doctor must always be in an on-call (standby) state.”
Currently, two doctors, Alice and Bob, are on-call (on_call = true).
At this time, Alice and Bob coincidentally feel unwell at the same time and want to get off the on-call shift, starting a shift change transaction from their respective terminals.
[Transaction Flow (Under Snapshot Isolation)]
- [Tx1: Alice] Acquires a snapshot. Confirms that there are currently two people on-call: Alice and Bob.
SELECT count(*) FROM doctors WHERE on_call = true;-> Result: 2 - [Tx2: Bob] Acquires a snapshot. Similarly confirms that there are two people: Alice and Bob.
SELECT count(*) FROM doctors WHERE on_call = true;-> Result: 2 - [Tx1: Alice] Judges that the rule (1 or more on-call) is met, and removes herself from on-call.
UPDATE doctors SET on_call = false WHERE name = 'Alice'; - [Tx2: Bob] Similarly judges that the rule is met, and removes himself from on-call.
UPDATE doctors SET on_call = false WHERE name = 'Bob'; - [Tx1: Alice] Commit successful.
- [Tx2: Bob] Commit successful. (Since Alice and Bob are updating different records, row locks do not conflict)
[Result] As a result of both Tx1 and Tx2 being committed, the number of doctors on-call has become “0”. The business rule has collapsed.
This is Write Skew. If it were Serializable, either Tx1 or Tx2 would be executed serially first, so the transaction executed later would have detected that the number of on-call doctors was “1” and could have aborted (rolled back) its operation to remove itself. However, in Snapshot Isolation, because they are updating mutually different data rows (the Alice row and the Bob row), no collision is detected, causing an inconsistency in the business rules.
3.3 ReadOnly Anomaly
Furthermore, in Snapshot Isolation, there is also an extremely peculiar anomaly called ReadOnly Anomaly where serializability breaks down due to the intervention of a “read-only transaction.” Shown in examples such as bank account deposit balances and interest accrual, this anomaly is a phenomenon where, despite no conflict occurring between update transactions, a read-only transaction looking at a past snapshot ends up reading a “logically impossible state in the timeline.” Because of the existence of these anomalies, Snapshot Isolation is distinguished from Serializable in a strict sense.
Chapter 4: The Operating Principle of MVCC (Multi-Version Concurrency Control)
We have discussed the theory of isolation levels and anomalies up to this point, but how do modern databases control these? The core technology for this is MVCC (Multi-Version Concurrency Control).
4.1 “Reads Do Not Block Writes, and Writes Do Not Block Reads”
The biggest design philosophy of MVCC, and its decisive difference from lock-based control (2PL), lies in the point that “reads and writes do not block each other.” When updating a record, an MVCC database does not overwrite the existing record directly (In-place update). Instead, it creates a new version of the record (tuple) while simultaneously keeping the old version of the record.
Multiple versions of the same record (a history from the past to the present) will exist simultaneously within the database. When a transaction reads data, it calculates and reads the “correct past version it should read” out of the numerous versions existing in the system, based on its own “Transaction ID (XID)” and “Start Time (Timestamp).”
Thanks to this, even while a transaction is rewriting a record, other transactions can read the “past version before it was rewritten,” avoiding waiting for locks.
4.2 Tuple Version Management Chain and Visibility Rules
The most important algorithm in MVCC is the Visibility Rule, which determines “which transaction can see which version of the data.”
Each transaction is assigned a monotonically increasing, unique Transaction ID (XID) at the start. Each version (tuple) of a record stored in the database is given the following information as metadata:
- Creation XID: The XID of the transaction that created this version via INSERT/UPDATE.
- Deletion XID: The XID of the transaction that logically deleted (invalidated) this version via UPDATE/DELETE.
When a transaction $T_i$ reads a data row, it determines visibility based on the following basic rules:
- Is it committed?: Has the transaction of the Creation XID already committed?
- Is it not in the future?: Is the Creation XID from a transaction in the past relative to the time $T_i$ started?
- Is it not deleted?: Is the Deletion XID not set, or is the transaction of the Deletion XID not yet committed, or is it a transaction from the future relative to the start time of $T_i$?
By strictly evaluating these conditions, a consistent snapshot is provided to each transaction.
Chapter 5: The Decisive Differences in MVCC Implementation Between PostgreSQL and MySQL (InnoDB)
Even though the basic principles of MVCC are the same, its internal implementation differs astonishingly depending on the database product. Here, we will comparatively dissect the MVCC architectures of PostgreSQL and MySQL (InnoDB), the two pillars of the open-source world.
5.1 PostgreSQL’s MVCC Implementation: In-Heap Append and the Inevitability of VACUUM
PostgreSQL’s MVCC adopts a highly unique and intuitive “Append-only architecture.”
5.1.1 Bit Judgment Logic by xmin and xmax
Inside the data file (heap) that is the actual entity of a table in PostgreSQL, two transaction IDs called xmin and xmax are recorded in the header of each row (tuple).
xmin(Transaction ID of Insert): The XID of the transaction that created this tuple.xmax(Transaction ID of Delete): The XID of the transaction that deleted this tuple (or logically deleted the old version via update).
[Behavior of the UPDATE Operation]
In PostgreSQL, an UPDATE is logically processed as a combination of DELETE and INSERT.
- Write the current transaction XID to the
xmaxof the old tuple. (Logical deletion) - Create an entirely new tuple in the free space of the heap, write the new data, and set the current transaction XID in
xmin. (New addition)
In other words, both the old and new tuples are stored mixed together within the same table data file (heap).
5.1.2 Massive Advantages and Fatal Challenges: The Existence of VACUUM
The biggest advantage of this architecture is that rollbacks are extremely fast. If a transaction aborts, the added tuples just need to be treated as “uncommitted,” and no data write-back processing is necessary.
However, a fatal challenge is the “Bloat of Dead Tuples.”
When UPDATEs and DELETEs are repeated, old versions of tuples that are no longer referenced by anyone (tuples where xmax has become a committed old transaction ID) will accumulate endlessly within the heap. If left alone, the physical size of the table will expand explosively, and the performance of sequential scans will suffer devastatingly.
The system process to physically delete these dead tuples and make the free space reusable is VACUUM (and the automatically executed autovacuum daemon). The reason tuning VACUUM is considered extremely important in PostgreSQL operations stems from the very foundation of this MVCC architecture.
5.2 MySQL InnoDB’s MVCC Implementation: In-Place Updates and Dynamic Reconstruction of Undo Logs
On the other hand, InnoDB, the default storage engine of MySQL, adopts an architecture closer to Oracle Database, utilizing “In-place updates and Undo Logs (Rollback Segments).”
5.2.1 Clustered Indexes and In-Place Updates
InnoDB tables are structured as B+Trees (clustered indexes) based on the primary key.
When an UPDATE is executed in InnoDB, it does not append a new row like PostgreSQL, but rather directly overwrites (In-place update) the data row on the B+Tree.
So, what happens if another transaction wants to read a past snapshot? For that purpose, InnoDB saves the “old data” from before the overwrite to a dedicated area called the Undo Log (Undo Log Segment).
5.2.2 Dynamic Reconstruction of the Past via Roll Pointers
The hidden columns of each data row in InnoDB include the following two:
DB_TRX_ID: The ID of the transaction that last inserted or updated this row.DB_ROLL_PTR(Roll Pointer): A pointer indicating the location within the Undo log where the “one version older” state of this row is stored.
The process by which a transaction reads a past snapshot is as follows:
- Read the latest data row from the B+Tree.
- Check the
DB_TRX_ID, and if it is an update by a transaction in the future relative to its own snapshot, determine that this latest row must not be read. - Follow the
DB_ROLL_PTRto retrieve the past version of the data from the Undo log. - Using the data in the Undo log, dynamically reconstruct (Rollback in memory) the state of the past record in memory.
- If it is still a future update, traverse the Undo log chain further into the past.
5.2.3 Advantages and Challenges of InnoDB
The advantage of this architecture is that the main table area (tablespace) is less prone to bloating. The latest data is always in the appropriate location in the B+Tree, and past versions are isolated in a separate area (Undo log), so physical scanning efficiency is kept high (large-scale VACUUMs like in PostgreSQL are unnecessary, and an Undo log purge process runs lightly in the background).
On the downside, if there are long-running transactions (such as batch processing or mysqldump) that read massive amounts of past snapshots, the overhead of traversing deeply into the Undo logs to reconstruct data occurs, degrading read performance. Also, it carries the risk of the Undo log itself bloating and compressing disk space.
Chapter 6: Serializable Snapshot Isolation (SSI) and the Forefront of Distributed Databases
The evolution of MVCC does not end here. As explained in Chapter 3, Snapshot Isolation (SI) had anomalies like “Write Skew” and was not completely Serializable. However, to relieve application developers from being conscious of the complexity of concurrency, complete Serializable must be realized while maintaining the high performance of MVCC.
6.1 The Birth of Serializable Snapshot Isolation (SSI)
In 2008, a groundbreaking algorithm called “Serializable Snapshot Isolation (SSI)” was published in a paper by Michael Cahill and others. This is a technology that guarantees complete serializability (Serializable) while based on the MVCC architecture. From version 9.1, PostgreSQL quickly adopted this SSI as the implementation for the “Serializable” isolation level.
The Operating Principle of SSI: Conflict Graphs and Dangerous Structures (rw-antidependency)
SSI does not perform blocking via locks. Instead, it closely tracks “which data was read (Read) and which data was written (Write)” during the execution of a transaction.
SSI monitors conflict relationships between transactions and looks for specific conflict patterns called “rw-antidependency (read-write antidependency).” Specifically, it is a relationship where a transaction $T_1$ reads a past version of data, and that data is later overwritten and committed by another transaction $T_2$. SSI internally builds a transaction conflict graph, and the moment it detects a “structure with two consecutive rw-antidependency arrows (dangerous structure),” it judges that serializability may collapse, and forcibly aborts (rolls back) one of the transactions.
By doing this, it stops transactions before anomalies like Write Skew (e.g., the doctor’s on-call problem) occur, resulting in a guarantee of complete Serializable. It can be called the ultimate form of Optimistic Concurrency Control (OCC).
6.2 MVCC in Distributed Databases: Spanner, CockroachDB, TiDB
Modern database technology has transcended the limits of single servers, evolving into distributed SQL databases (NewSQL) distributed across data centers worldwide. In a distributed environment, realizing MVCC with global consistency was also a challenge against the laws of physics.
Google Spanner and the TrueTime API
Google’s Spanner developed the TrueTime API to solve the transaction ordering problem in distributed systems. Under the premise that the clocks (physical clocks) of each server will inevitably drift (clock skew), it combines GPS and atomic clocks to provide the current time as a “range of uncertainty (time window).” By having Spanner’s MVCC wait for this TrueTime uncertainty window to pass at the time of transaction commit (Commit Wait), it physically guaranteed that “transactions with causal relationships will always have correct timestamp ordering (External Consistency).”
CockroachDB and HLC (Hybrid Logical Clock)
CockroachDB, an open-source distributed database inspired by Spanner, adopts an HLC (Hybrid Logical Clock) to achieve similar consistency without using expensive atomic clocks. By combining physical clock synchronization via NTP and Lamport logical clocks (counters based on causal relationships between events), it generates globally consistent MVCC snapshot timestamps across distributed nodes, realizing SSI (Serializable Snapshot Isolation) in a distributed environment.
TiDB and the Percolator Model
TiDB, developed by PingCAP, adopts a distributed transaction model based on the Google Percolator model. It has an architecture that provides a single component (Placement Driver: PD) that dispenses global timestamps, and the storage engine (TiKV) of each node uses those timestamps to process MVCC locally. While based on 2PC (Two-Phase Commit), it minimizes the holding period of locks, balancing giant transactions and MVCC in a distributed environment.
Conclusion: Beyond ACID
Database transaction isolation levels are by no means just items to memorize by rote. They are the very history of a decades-long struggle in computer science to harmonize the conflicting demands of data consistency and system performance.
From the incomplete definitions of ANSI SQL-92, to the dramatic improvements in concurrency processing via MVCC, the divergence of architectures between PostgreSQL and InnoDB, and the challenge for ultimate consistency via SSI and distributed databases. Deeply understanding these internal structures should serve as a powerful weapon for designing more robust and high-performing applications.
We now live in an era where ACID properties are not just a “myth” but are implemented as a “reality” through advanced algorithms and physical clock synchronization. For engineers navigating the sea of data, knowing the abyss of database engines is a journey of intellectual exploration that never truly ends.